In a busy room, several people talk at the same time. This group project puts one phone on the table to work out who is speaking, separate the voices, and transcribe the conversations for hearing-impaired listeners.
My part
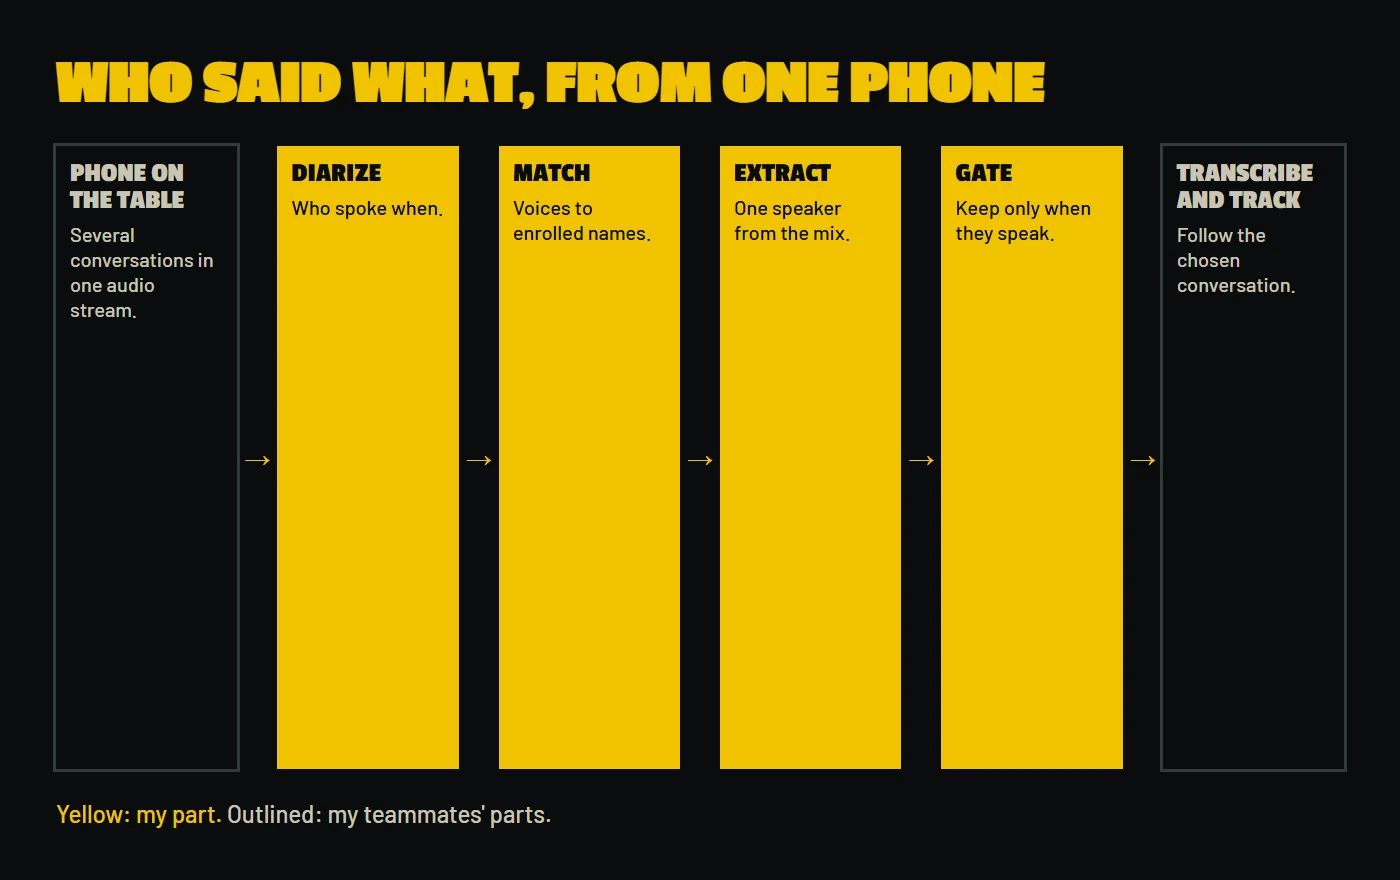
My teammates handle capture, transcription, conversation tracking and the interface. I own two steps:
- Speaker diarization: working out who spoke when.
- Speaker separation: extracting the voice of an enrolled speaker from the mix.
The approach so far
I fine-tune pretrained models instead of training from scratch, starting from pyannote. The pipeline runs in order: diarize, match voices to enrolled names, extract each speaker, then gate. It starts offline, measured with DER and SI-SDR. Streaming comes later.
This project is still running, so there are no final results yet.