Complaints about high rent and complaints about bad data-entry software sound equally angry, so sentiment analysis cannot tell them apart. Only one of them can be solved with software. This project looks for that difference.
The pipeline
- Filter. A zero-shot RoBERTa classifier removes obvious noise like personal venting.
- Cluster. BERTopic groups what remains into topics, with no fixed number of clusters.
- Verify. A small quantized LLM reads each cluster’s keywords and sample posts, then decides whether it is a solvable problem or just noise.
What it found
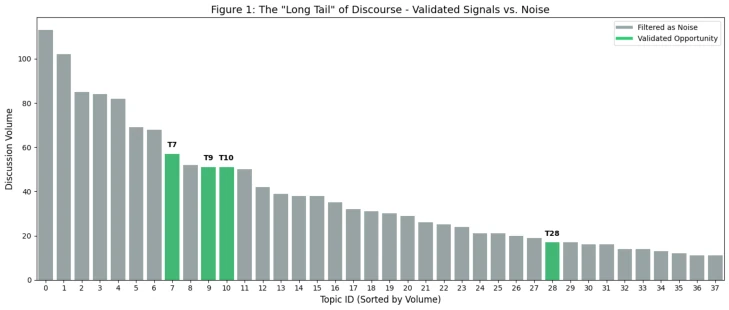
The largest clusters were about money and relationships, and the LLM rejected them despite their strong negative tone. Smaller clusters passed, such as marketing teams losing time on client reporting, and the manual checking AI-written text still needs.
Limits
The first filter is modest, with an F1 of 0.62 on a small hand-labelled sample. Reddit also leans towards complaints, and a small LLM can hallucinate, so I would treat its verdicts as leads to check.