CLIP is trained on web photos, so it has no idea what a runway looks like from directly overhead. We fine-tuned it on satellite image captions, then tested it on a hidden set of 21 classes. Only 7 of those class names appear in the training data, so the model has to transfer what it learned.
My part
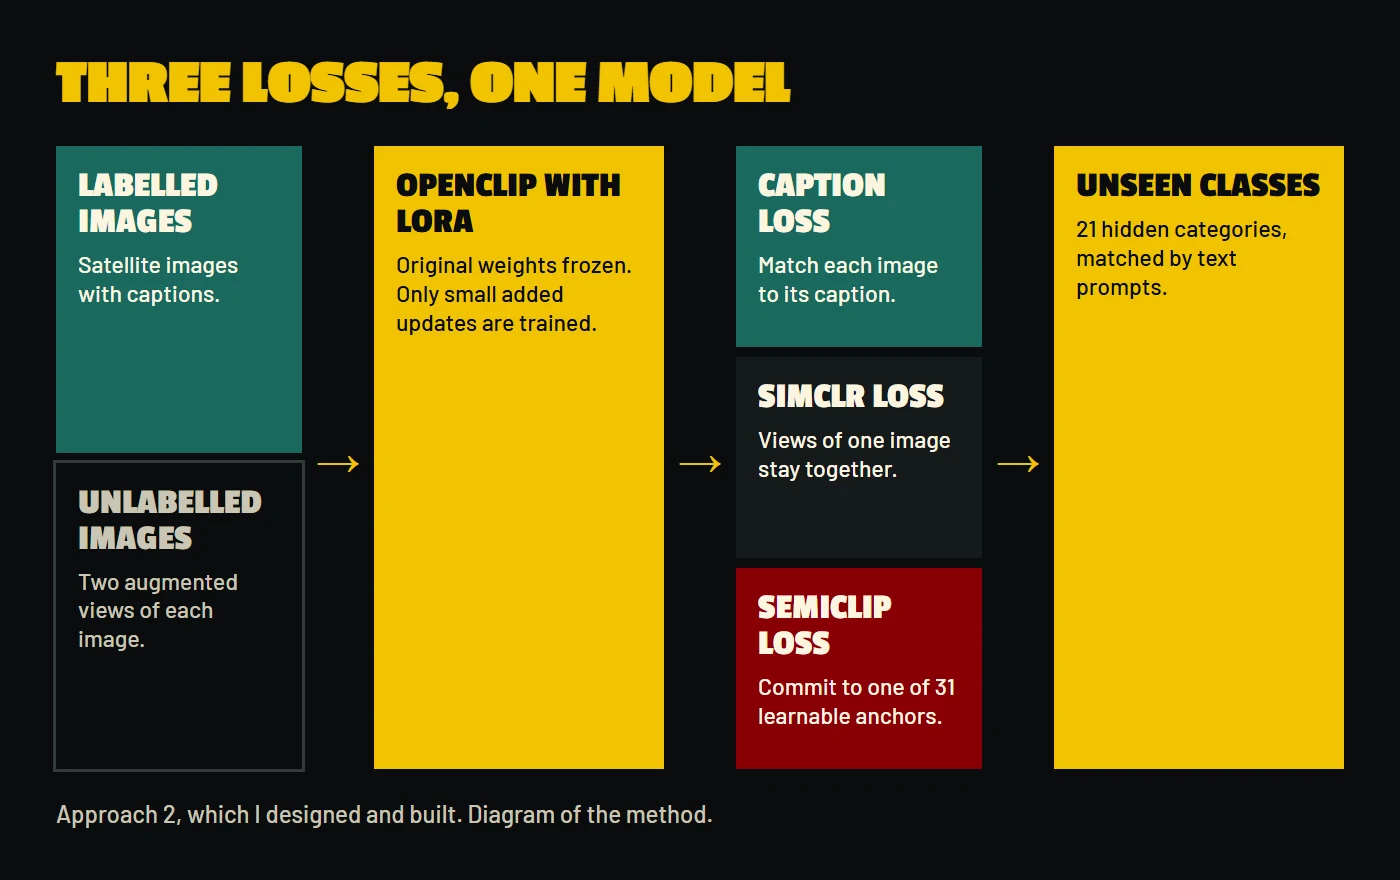
We were a team of four, and each of us owned a part. I designed and built Approach 2 on my own:
- SemiCLIP, a new entropy-minimisation loss over 31 learnable text anchors, which pushes each unlabelled image to commit to one anchor.
- A three-part loss combining the caption loss, SimCLR and SemiCLIP, with a schedule that holds SemiCLIP back for the first 15 epochs. Starting it earlier collapsed the anchors.
- The study comparing each loss under matched conditions, and the retrieval evaluation.
What I found
Each extra loss hurt when used alone, but together they beat supervised-only training. This only showed up once the comparison matched the full training conditions. An earlier 20-epoch run gave the opposite answer, because SemiCLIP had barely switched on.
Each result comes from a single training seed, so small differences are indicative only.