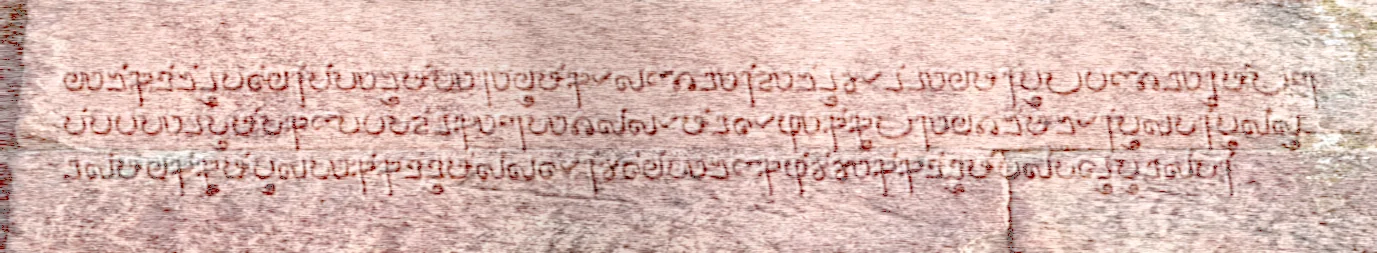
Tamil was once written in scripts that very few people can read today. Tamili and Vattezhuthu survive on stone, which is cracked and worn. Vision-language models have never seen them, and their tokenizers do not even contain the characters.
Building the data
No labelled dataset exists, so I built one. I took Tamil text from Project Madurai and converted it to the ancient scripts with Aksharamukha. I then blended the text onto stone backgrounds and added erosion, lighting changes and surface noise with Augraphy.
Two models, not one
One model doing both jobs converged poorly and did not fit in the 20 GB of GPU memory I had. So I split the work:
- Read the characters. Qwen2.5-VL-3B, fine-tuned with QLoRA at 4-bit on a balanced set of 6,000 clean image-text pairs. I built a custom tokenizer with 5,000 sub-word units and added the new tokens to the model, unfreezing the embedding and output layers so it could learn them.
- Restore the words. Ancient Tamil words fuse together with no spaces. A small Qwen2.5-0.5B model puts the boundaries back. Long inputs made it hallucinate, so I limited it to 15-word windows, which gave 25,611 training pairs.
Testing it honestly
The clean score is an upper limit, because those images match the training data. The stone images were held back as the harder test. The drop from 95.4 to 63.0 BLEU shows the real cost of visual noise. These are simulated stones, so real inscriptions are still an open test.